Insights

Most of the value is decided outside the model.

Whether a test can be trusted, what a model is worth, when people should follow it and what happens to a metric once it becomes a target. Each note explains the idea and lets you try it.

Method notes

Four ideas, each one interactive.

Synthetic data, illustrative numbers, a few minutes each.

experimentation

Will this test actually tell you anything?

Most A/B tests are decided before they start: too small to detect the effect that matters, or stopped the day they look good. Both produce confident wins that disappear in production.

Try this: Turn on daily peeking and count the false winners, then switch on CUPED and watch the required sample size fall.

Power analysis · Sequential testing · CUPED · Bayesian read-out
decision economics

What is a model actually worth?

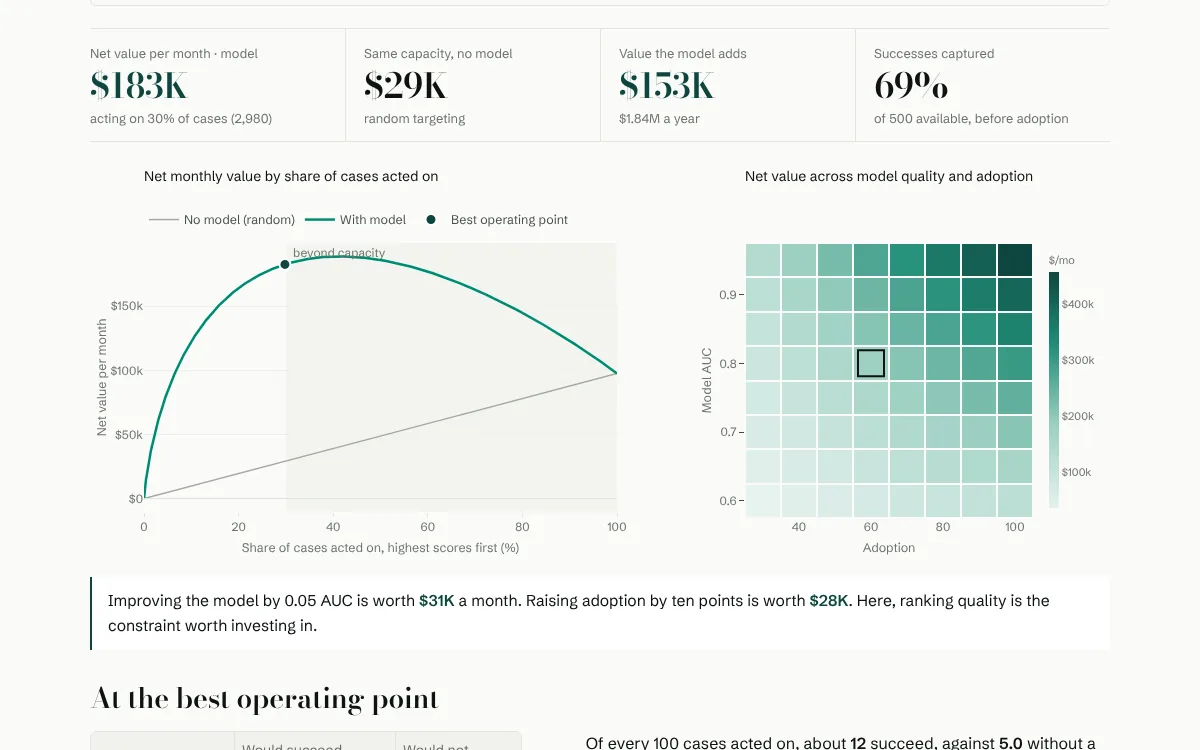
Model quality is the easiest number to improve and often the least valuable. Capacity, cost and adoption usually decide what a model is worth, and they are rarely in the business case.

Try this: Raise AUC, then raise adoption by the same effort, and see which moves net value more.

Operating curves · Value modelling · Sensitivity
human–AI collaboration

Do you know when to trust the model?

A recommendation only creates value when a person acts on it. People under-trust good models and over-trust bad ones in predictable ways, and workflow design can correct both.

Try this: Make ten calls with an AI adviser and get your own reliance profile: when you followed it and should have, and when you should not.

Judge–advisor design · Weight of advice · Calibration
measurement

When a measure becomes a target

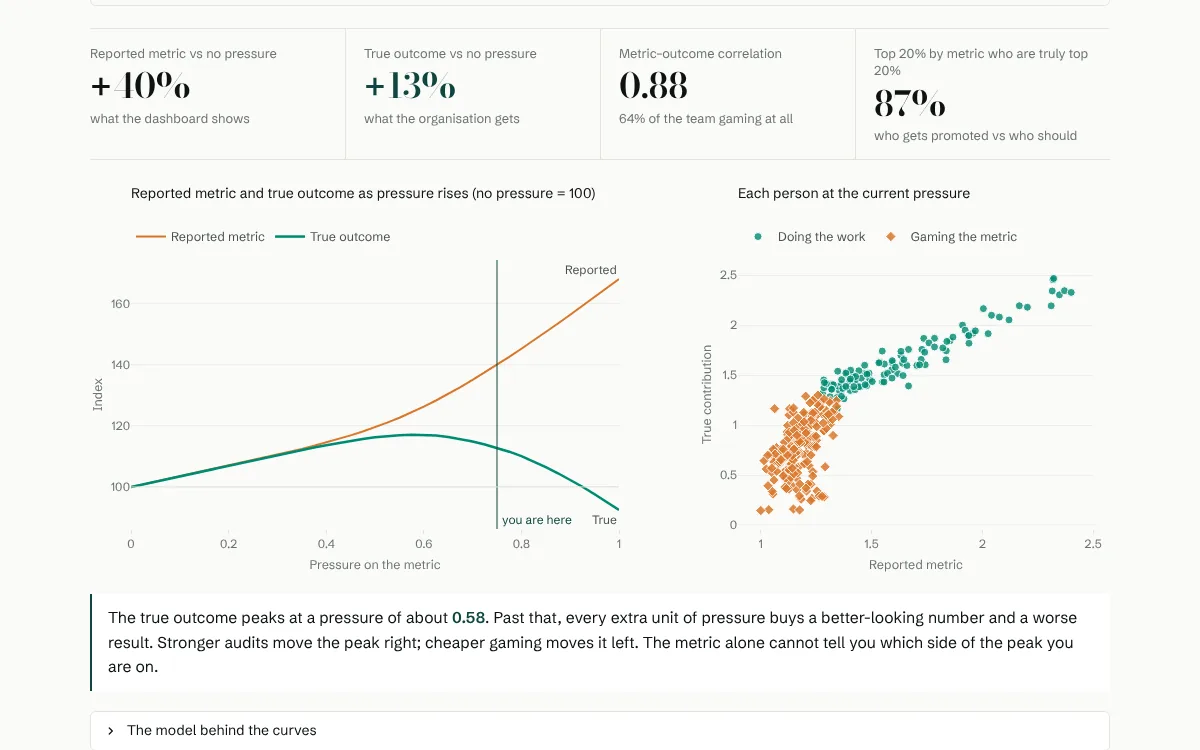
Every metric that becomes a target starts to drift from the outcome it was meant to track. The drift is quiet, because the dashboard keeps improving.

Try this: Increase the pressure on the team and watch the reported number and the real outcome part ways.

Agent simulation · Incentives · Metric validity
Put it to work

See these ideas inside a working product.

The pricing copilot uses all four: a properly powered test, value at measured adoption, recommendations people can check, and a success measure that cannot be gamed.

Decision Lab · live demo
Starting the demo…