The Lab
Projects that run, not slides about them.
15 working projects, each built around a real business decision, plus the method notes and tools behind them. Pick one and run it right here.
The projects
15 decisions, each one live.
-
01 · Models
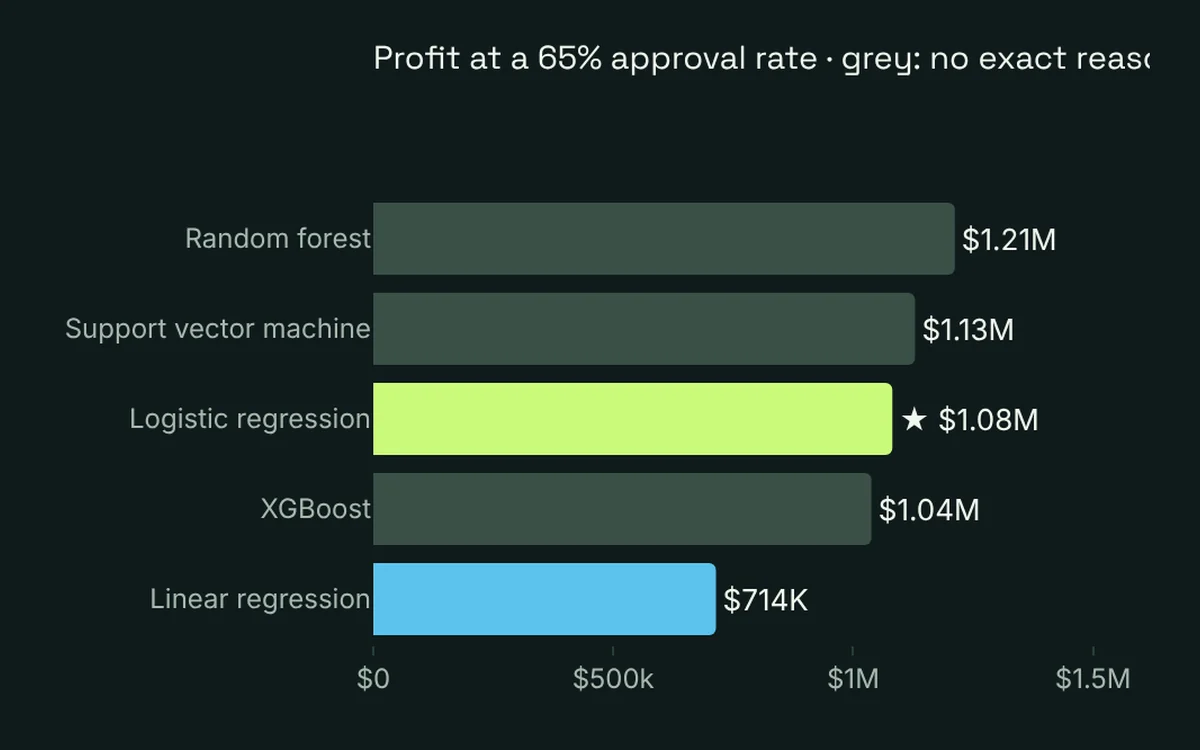
Lending decision lab
50,000 synthetic members
Run it here Lending decision lab (opens in a new tab) Project page Lending decision lab
-
02 · Models
Subscriber value lab
+$636K from targeting offers by uplift instead of risk
Run it here Subscriber value lab (opens in a new tab) Project page Subscriber value lab
-
03 · Models
Credit risk & loss lab
0.848 out-of-time AUC, ahead of the logistic benchmark
Run it here Credit risk & loss lab (opens in a new tab) Project page Credit risk & loss lab
-
04 · Models
Forecasting at scale
45% less forecast error than repeating last year
Run it here Forecasting at scale (opens in a new tab) Project page Forecasting at scale
-
05 · Models
Next best action
+$195K a month, estimated before launch
Run it here Next best action (opens in a new tab) Project page Next best action
-
06 · AI engineering
Analytics copilot
9 governed metrics, each with an owner
Run it here Analytics copilot (opens in a new tab) Project page Analytics copilot
-
07 · AI engineering
Credit policy assistant
89% of questions find the right section first
Run it here Credit policy assistant (opens in a new tab) Project page Credit policy assistant
-
08 · Products
Decision Story Studio
7 input formats, read in the browser
Run it here Decision Story Studio (opens in a new tab) Project page Decision Story Studio
-
09 · Products
Decision platform
12 data tests run on every build
Run it here Decision platform (opens in a new tab) Project page Decision platform
-
10 · Products
Pricing & demand copilot
7 stages, from framing to measured value
Run it here Pricing & demand copilot (opens in a new tab) Project page Pricing & demand copilot
-
11 · Data & decisions
Causal impact lab
−0.43 difference-in-differences vs a true −0.40
Run it here Causal impact lab (opens in a new tab) Project page Causal impact lab
-
12 · Data & decisions
Marketing mix optimizer
$1.9M a year in lifetime value, same budget
Run it here Marketing mix optimizer (opens in a new tab) Project page Marketing mix optimizer
-
13 · Data & decisions
Mortgage market intelligence
380+ U.S. metro markets scored
Run it here Mortgage market intelligence (opens in a new tab) Project page Mortgage market intelligence
-
14 · Data & decisions
Mortgage product strategy
3 product lines compared
Run it here Mortgage product strategy (opens in a new tab) Project page Mortgage product strategy
-
15 · Data & decisions
Lead prioritization
+38% more conversions from the same team, on synthetic data
Run it here Lead prioritization (opens in a new tab) Project page Lead prioritization
The console
Run it right here.
Choose “Run it here” on any project, note or tool and it loads below. Each app also opens full screen in its own tab.
Nothing loads from the app until you ask. A demo that has been idle sleeps, and takes about 30 seconds to wake.
Method notes
The ideas behind them.
Four short notes, each with a live demo you can try in a few minutes.
-
experimentation
Will this test actually tell you anything?
Most A/B tests are decided before they start: too small to detect the effect that matters, or stopped the day they look good. Both produce confident wins that disappear in production.
Try this: Turn on daily peeking and count the false winners, then switch on CUPED and watch the required sample size fall.
Power analysis · Sequential testing · CUPED · Bayesian read-out
Run it here Will this test actually tell you anything? (opens in a new tab)
-
decision economics
What is a model actually worth?
Model quality is the easiest number to improve and often the least valuable. Capacity, cost and adoption usually decide what a model is worth, and they are rarely in the business case.
Try this: Raise AUC, then raise adoption by the same effort, and see which moves net value more.
Operating curves · Value modeling · Sensitivity
Run it here What is a model actually worth? (opens in a new tab)
-
human–AI collaboration
Do you know when to trust the model?
A recommendation only creates value when a person acts on it. People under-trust good models and over-trust bad ones in predictable ways, and workflow design can correct both.
Try this: Make ten calls with an AI adviser and get your own reliance profile: when you followed it and should have, and when you should not.
Judge–advisor design · Weight of advice · Calibration
Run it here Do you know when to trust the model? (opens in a new tab)
-
measurement
When a measure becomes a target
Every metric that becomes a target starts to drift from the outcome it was meant to track. The drift is quiet, because the dashboard keeps improving.
Try this: Increase the pressure on the team and watch the reported number and the real outcome part ways.
Agent simulation · Incentives · Metric validity
Run it here When a measure becomes a target (opens in a new tab)
AI engineering
Models on the record.
Real model runs, recorded once and replayed exactly. Nothing calls a model when you open a page.
-
Larkspur Market (fictional)
Analyst agent
A model answers business questions by writing SQL against a read-only grocery warehouse: it finds the tables, checks its own errors and refuses what it should not do. Real runs, recorded once and replayed step by step.
Try this: Open Replay and step through one question: every tool call, the SQL it wrote and where it corrected itself.
Tool use · Read-only SQL · Write locks · Self-correction · Refusals · Cost and latency
-
release gate
LLM eval harness
A 30-case test set, rule-based graders and a scoreboard across models, then the failures read one by one and a release gate that says ship or hold.
Try this: Go to Release gate and see which model would ship, and which failure would stop it.
Test set · Rule-based graders · Scoreboard · Failure review · Release gate
-
accounts payable
Document intelligence
Forty synthetic invoices: extraction by a model against a live rules baseline, deterministic AP controls, a review queue for what should not pay itself, and the economics of the whole loop.
Try this: Open the Review queue: the invoices the controls held back, and why.
Extraction · Rules baseline · AP controls · Human review queue · Unit economics
Tools
One question, one minute.
They run in your browser and open at once. Nothing you enter or upload leaves your machine.
-
A/B test planner
Will this test actually tell you anything?
Sample size and duration before a test starts, and how often reading it early declares a false winner.
-
Model value calculator
What is this model actually worth?
AUC, capacity, the value of a hit, the cost of an action and adoption, turned into money per month and the best capacity.
-
Drift checker
Has the data moved under your model?
Load two CSVs, or one with a period column, and get a population stability index and a verdict for every input.
Open conversations