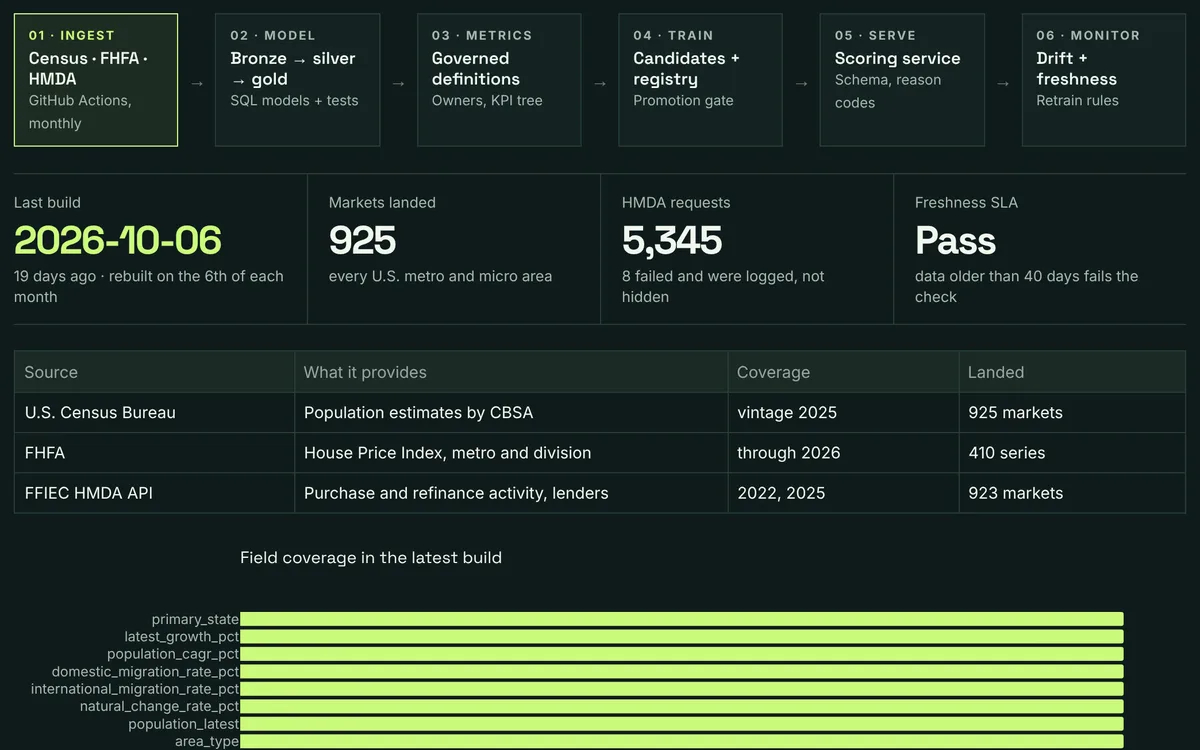
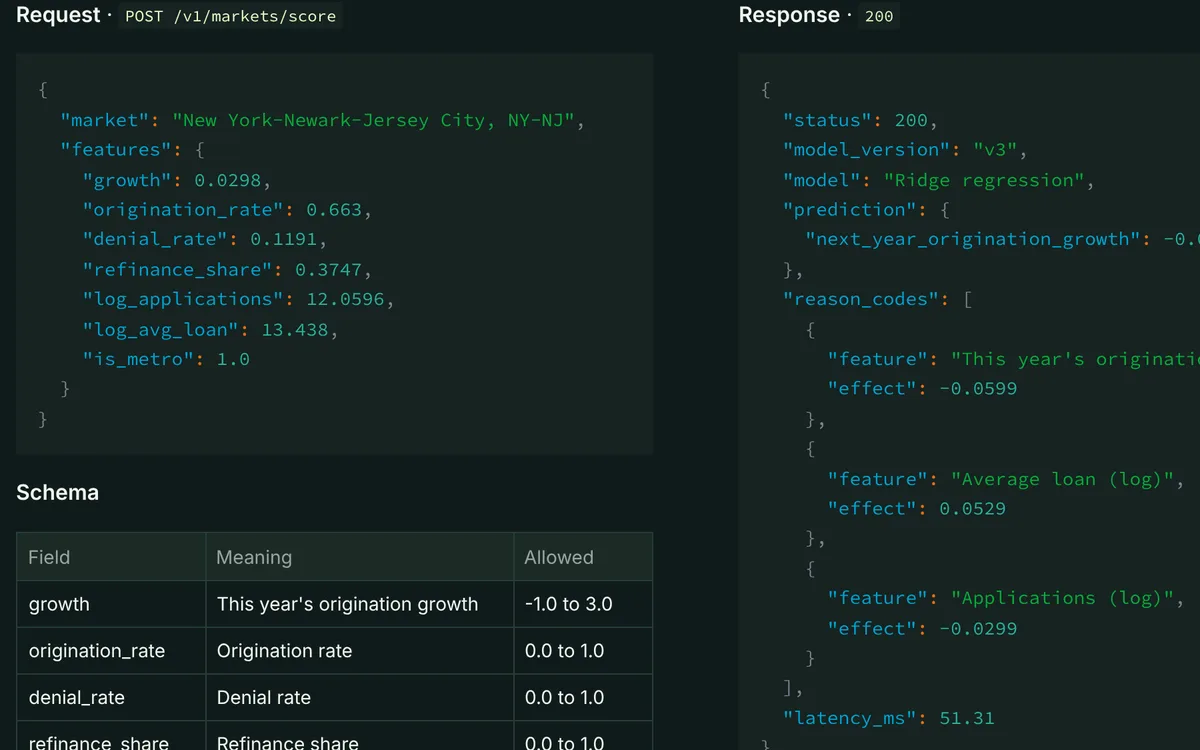
The engineering around a model: a scheduled pipeline, tested SQL models, governed metrics, a gated model, a scoring service and monitoring.
Decision platformPublic data7 decisions
12data tests run on every build
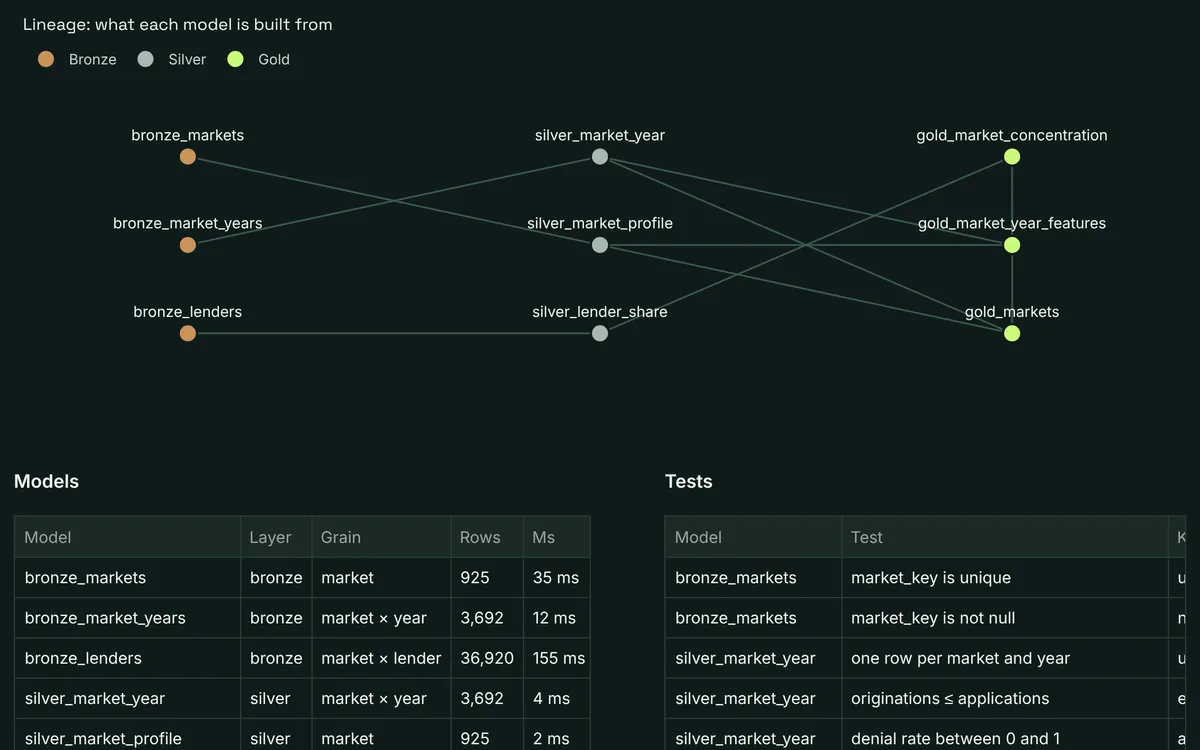
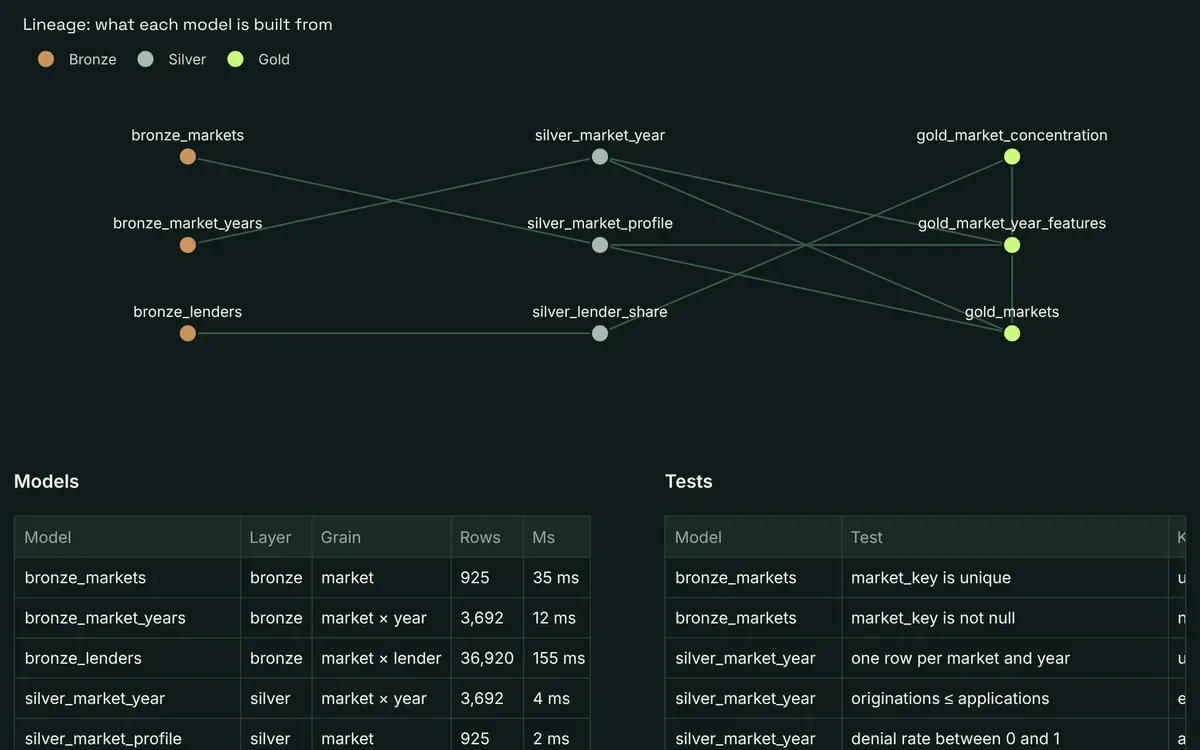
9SQL models from bronze to gold
4model versions, one promoted through the gate
7decisions, told step by step
4algorithms and methods used
The decision
Which U.S. markets will grow purchase lending next year, delivered by a system that keeps the answer fresh and trustworthy.
The problem
Most models fail in the plumbing, not the math: stale data, numbers defined differently in every report, a model nobody can trace back to its training data, and no signal when the world shifts under it.
The answer
Promote the model that ranks markets, not the one with the lowest error, because the decision is which markets to prioritize.
What it changed
1
Twelve data tests on every build, with warnings kept apart from failures that stop the line.
2
A model promoted by what the decision needs: it ranks markets with +3.4 points of top-decile lift, and its forecast error is written on the model card.
3
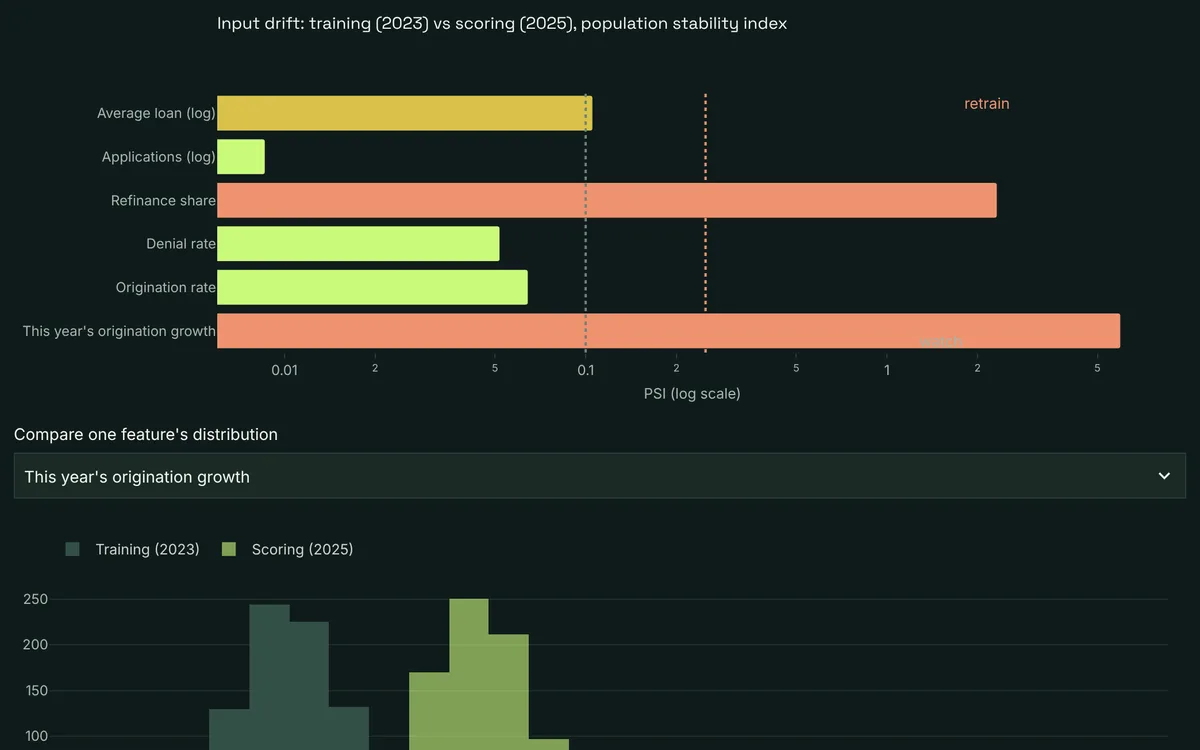
A retrain trigger that fires for a real reason: the inputs shifted after the rate shock.
Results come from public data. They show the method, not a client result.
Inside the lab
How it was proven
Public data only: U.S. Census Bureau population estimates, FHFA House Price Index and HMDA aggregates via the FFIEC Data Browser API.
Every table, metric, model and app in the platform, and how they connect. Click any object to walk its lineage, or run an incident drill: a late source, a schema change, a failed test, drift or a bad request, and see what the pipeline does about it.